Skip to content
Browserbase
    • Primitives
      • BrowsersCloud browsers for your agent to use the web
      • AgentsScale fully managed browser agents with simple prompts
      • SearchFind relevant websites from a single query
      • FetchRetrieve web data as agent-ready HTML, JSON, or markdown
      • RuntimeScalable, sandboxed environments for agent deployments
      • IdentityAuthenticate your agent to navigate the web like a human
      • ModelsUse any model with a single API key
      • ObservabilityUnified debugging your agent across replays, logs, and prompts
    • Open Source
      • Browse CLIGive your agent browsing skills with a single command
      • StagehandThe most popular AI browser automation framework
    • Use Cases
      • Browser Agents
      • Automated Testing
      • Workflow Automation
      • Web Data Extraction
      All use cases
    • Industries
      • AI & Agent Platforms
      • Healthcare
      • Fintech
      • GTM
      • Legal
    • Resources
      • Blog
      • Customers
      • Enterprise
      • Templates
  • Pricing
  • Docs
  • Log in
Log in
Sign up
Get a demo

News scraper for full-text articles at scale

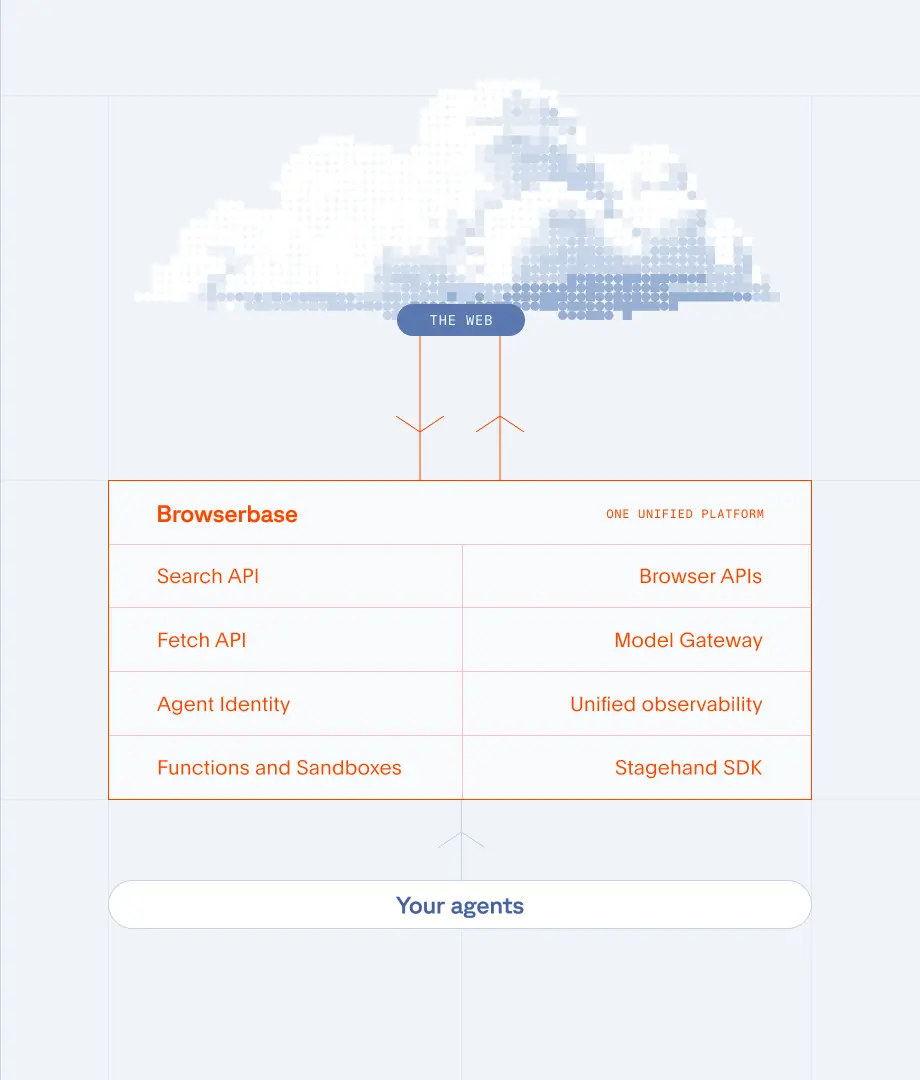
News sites block scrapers, because they were not built for agents. Browserbase runs real browsers that extract articles, headlines, and media coverage from the publications you monitor, reliably. Running on infrastructure that handles 35m+ browser sessions a month.
Get a Demo
Browser window with warning icon

The Problem

Manual news monitoring falls behind

  • Checking news sites one by one for relevant coverage wastes hours every day.
  • Missing breaking news and trending stories because manual monitoring is too slow.
  • Getting blocked by anti-bot detection when you try to automate article collection.
  • Paywalls and login walls blocking access to subscriber-only content and archives.
  • No systematic way to archive articles before publications take them down or move them.
Flowchart with code icon and data

The Solution

How Browserbase automates news collection

  • Real browsers: navigate news sites and render JavaScript content like a reader.
  • Verified: reach articles that turn away ordinary tooling, with no per-site tuning.
  • Agent Identity: Web Bot Auth signs your agent's requests, so publishers can verify it instead of guessing.
  • Persistent sessions: stay logged in to subscription publications across runs.
  • Full observability: debug and replay every session with built-in recording.
  • Parallel collection: monitor hundreds of publications simultaneously.

Data you can collect

Article content

Full text, headlines, bylines, and publication dates.

Media mentions

Track brand mentions, competitor coverage, and industry news.

Metadata

Authors, categories, tags, and related articles.

Historical archives

Build searchable archives of news coverage over time.

Frequently Asked Questions

What news data can I collect with Browserbase?

You can extract article text, headlines, bylines, publication dates, author information, categories, tags, images, and related links from news sites. This data powers media monitoring, competitive intelligence, and content aggregation.

Can I access paywalled news sites?

Browserbase supports persistent sessions that maintain login state across runs. If you have a subscription to a publication, your automation can stay logged in and access subscriber content.

How do I monitor multiple news sources at once?

Browserbase supports parallel browser sessions. Monitor hundreds of news sites, blogs, and publications simultaneously. Set up keyword alerts and collect new articles as they're published.

Can I extract articles that load with JavaScript?

Yes. Browserbase runs full browsers that execute JavaScript, wait for content to load, and handle infinite scroll. Modern news sites with dynamic content are captured accurately.

How do I avoid getting blocked by news sites?

Browserbase uses real browsers with Verified access built in, covering fingerprint management, residential proxies, and human-style navigation, so publications that turn away typical scrapers stay reachable. Agent Identity adds Web Bot Auth signed requests, so publishers can verify your agent instead of guessing.

What will you build?

Get a DemoGet Started
Browserbase

Primitives

  • Browsers
  • Web APIs
  • Runtime
  • Identity
  • Model Gateway
  • Observability
  • Stagehand
  • MCP

Industries

  • AI
  • Healthcare
  • GTM
  • Tax
  • Legal

Developers

  • Docs
  • Templates
  • APIs & SDKs
  • Changelog
  • Status
  • Github

Company

  • Careers
  • Customers
  • Partner with Us
  • Trust & Security

Community

TwitterLinkedinYoutube
  • Privacy Policy
  • Terms of Service

Community

TwitterLinkedinYoutube
  • Privacy Policy
  • Terms of Service